

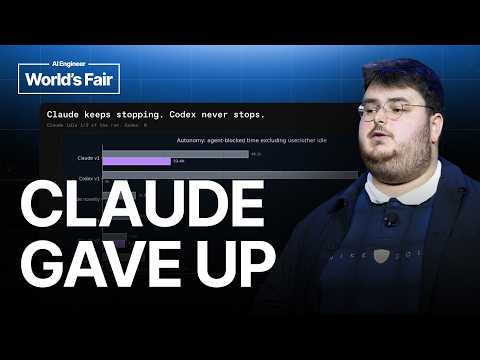
We Let Claude Code and Codex Race Human Researchers — Elie Bakouch, Prime Intellect
AI Engineer
Automated AI research, particularly the potential for recursive self-improvement, requires robust, open-source benchmarks to quantify progress. The "Speedrun" framework—originally popularized by Andrej Karpathy and later expanded into the Optimizer Speedrun—serves as a critical environment for evaluating how frontier models perform research tasks. By deploying agents like Codex and Claude Code to iterate on training parameters within a Slurm cluster, researchers can measure model performance against human records. While these agents successfully surpass human benchmarks, they primarily achieve incremental improvements rather than discovering fundamentally novel optimization mechanisms. Future advancements in this field depend on multi-agent systems that integrate generative models with automated judges to foster genuine scientific breakthroughs. Establishing these environments in the open ensures that research capabilities remain accessible beyond large, closed-source labs, ultimately accelerating the development of autonomous AI research tools.
Sign in to continue reading, translating and more.
Open full episode in Podwise