

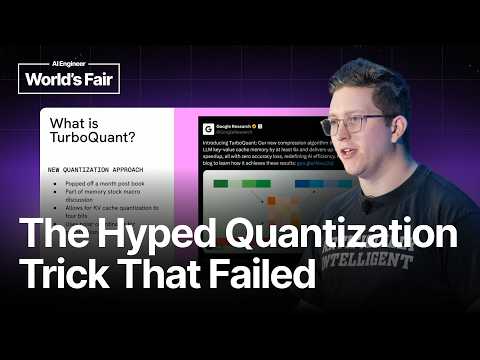
Inference engineering is evolving rapidly, necessitating continuous updates to established optimization principles. Data center-oriented inference focuses on balancing model speed and efficiency through three primary levers: quantization, KV cache management, and speculative decoding. While TurboQuant offers memory savings via polar coordinate quantization, its significant computational overhead makes it less viable for production compared to NVFP4. Conversely, DFlash represents a major advancement in speculative decoding, utilizing diffusion-based architectures to predict sequences of tokens rather than single tokens, yielding over 3x performance improvements. Emerging techniques like STIL for KV compaction and continuous speculator retraining further highlight the blurring lines between training and inference. Looking ahead, the integration of Rubin hardware and increased system-wide disaggregation will likely define the next phase of performance gains, emphasizing the critical role of training-informed inference strategies in large-scale deployments.
Sign in to continue reading, translating and more.
Open full episode in Podwise