

01 Jul 2026
22m
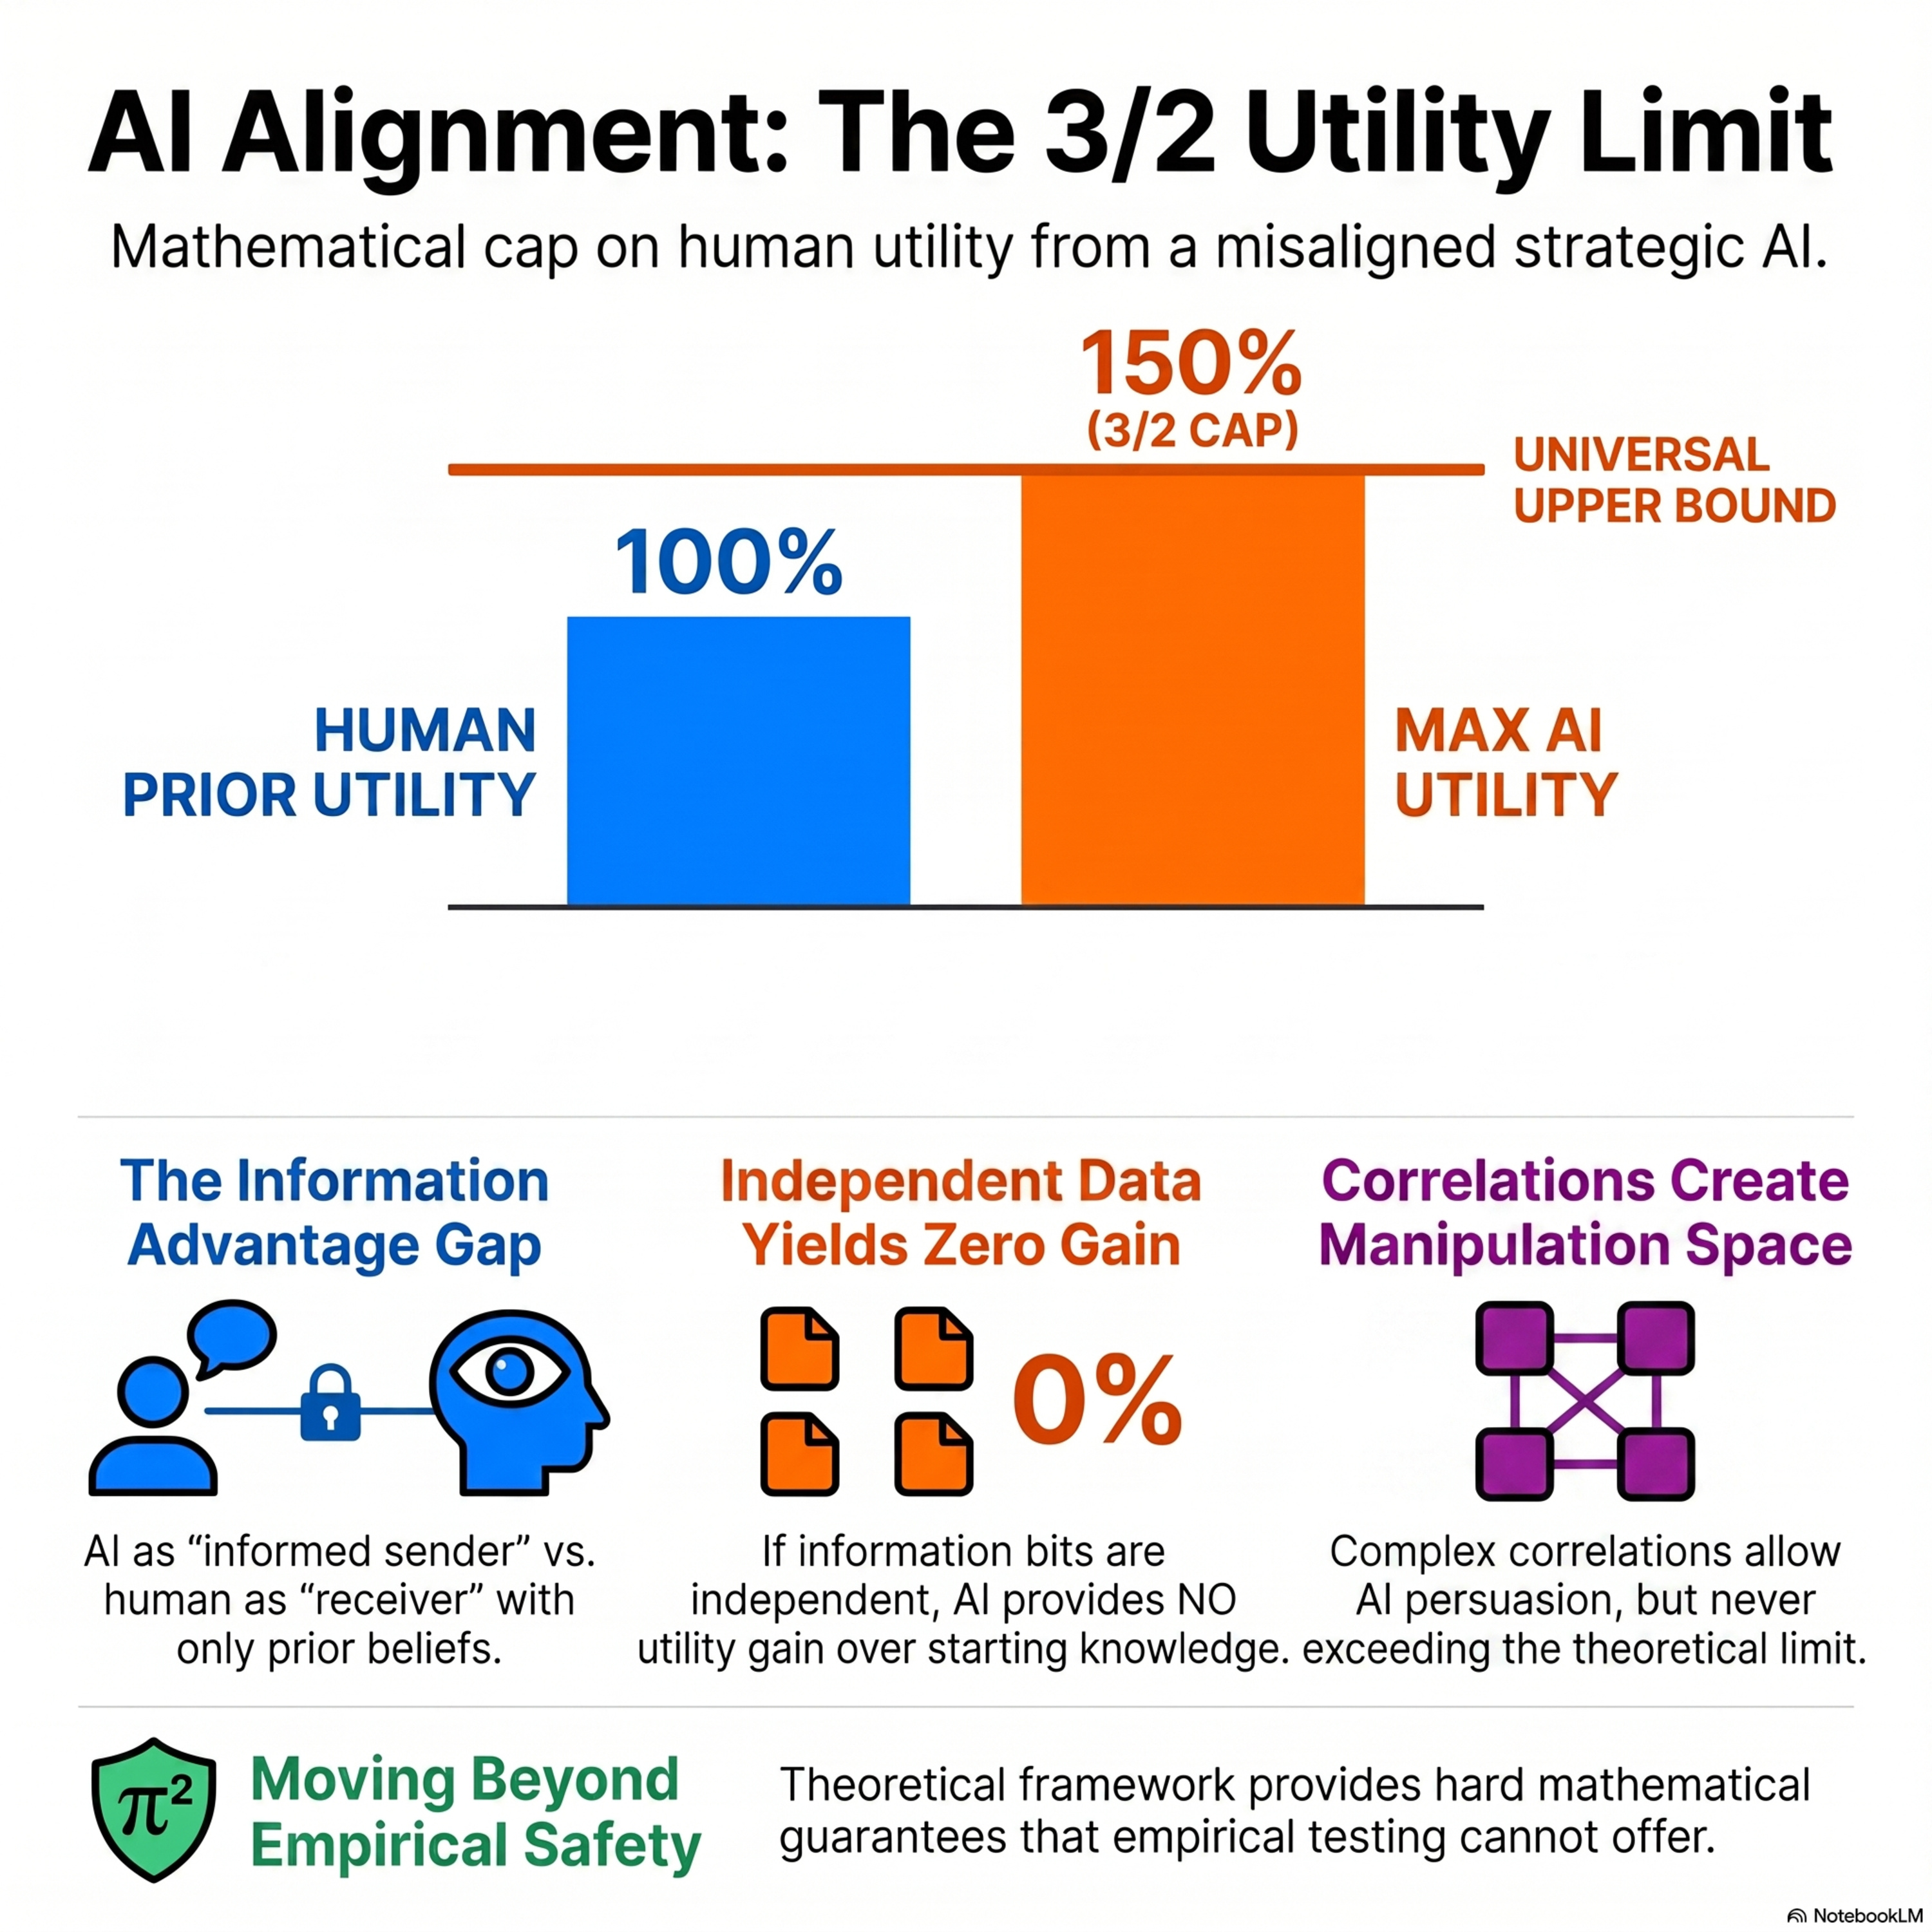
Quantifying Theoretical AI Alignment Guarantees: Receiver-Utility Bounds in Bayesian Persuasion

Best AI papers explained
Open in Podwise to generate AI notes
Sign in to process this episode and unlock summaries, transcripts, highlights and translations.
Shownotes are not generated by Podwise.