

05 Mar 2026
1h 3m
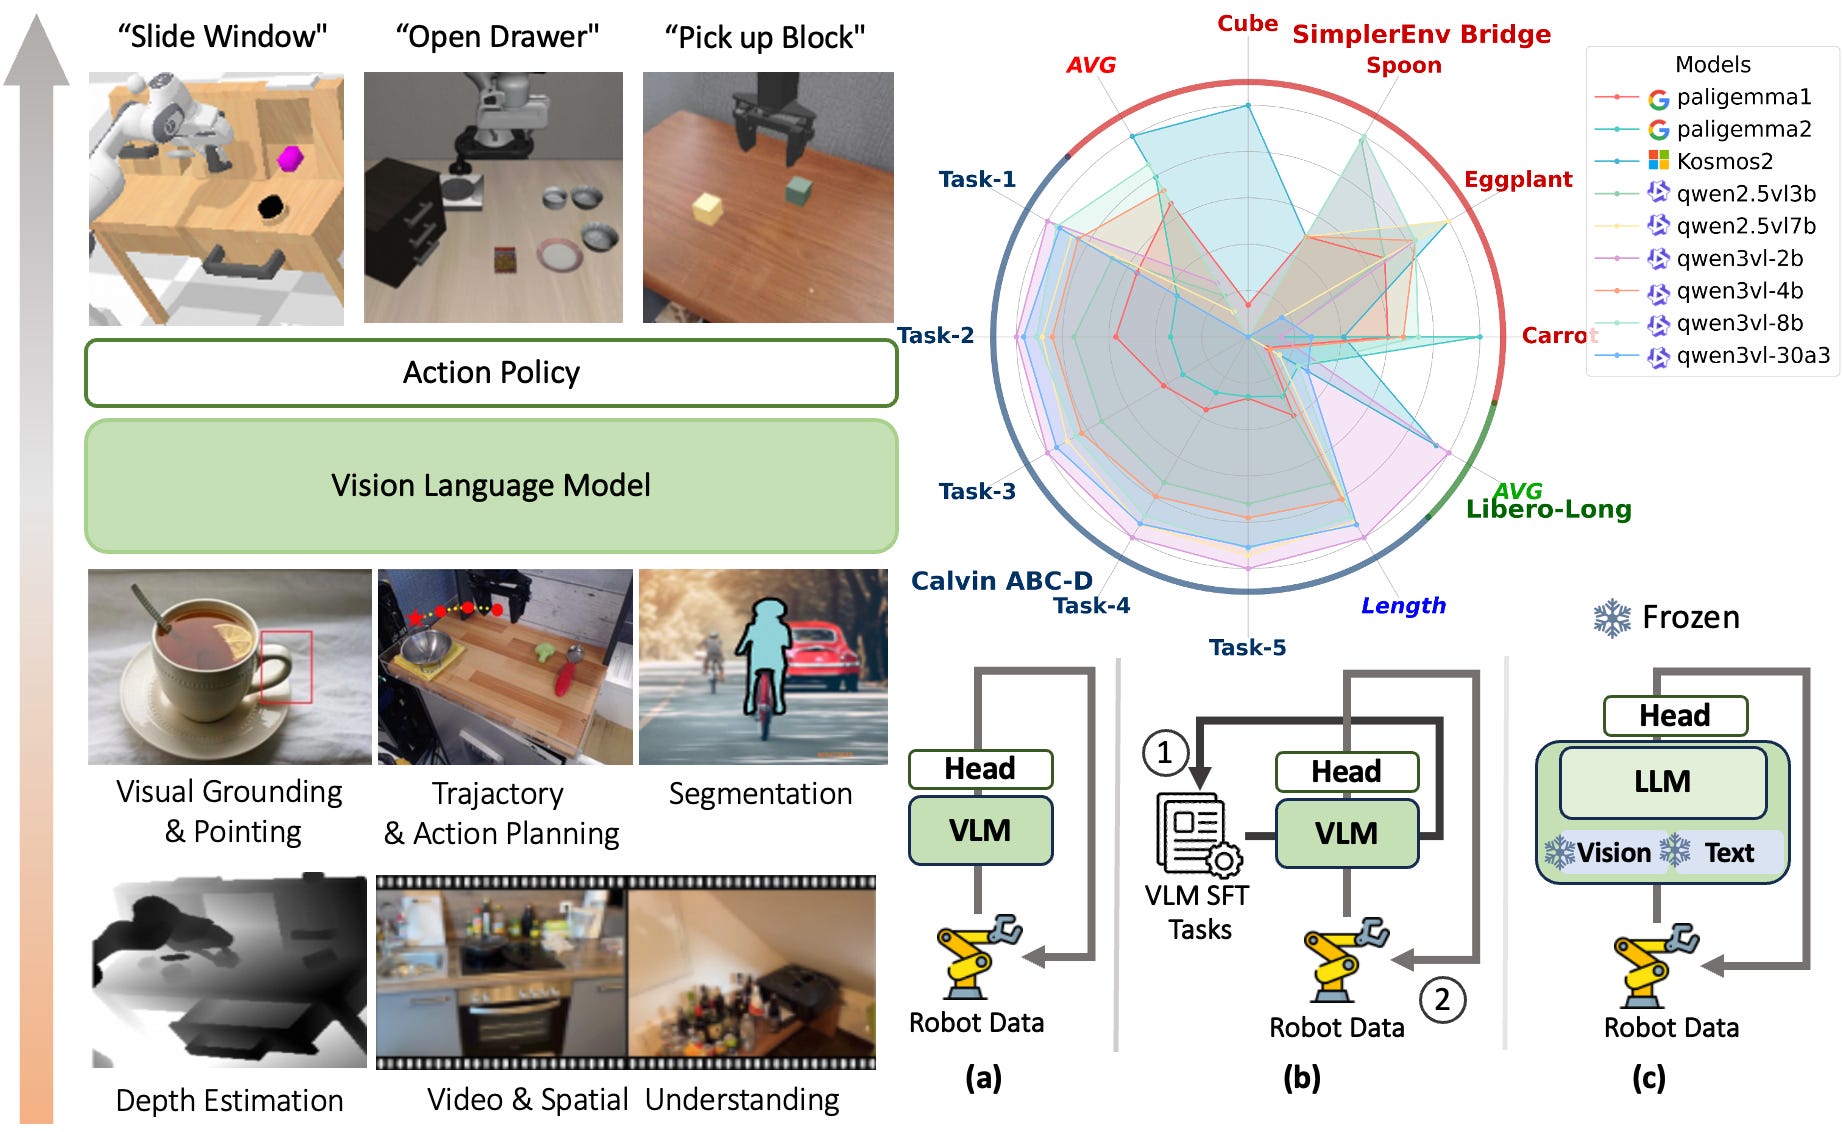
Ep#65: VLM4VLA: Revisiting Vision-Language Models in Vision-Language-Action Models
RoboPapers
Open in Podwise to generate AI notes
Sign in to process this episode and unlock summaries, transcripts, highlights and translations.
Shownotes are not generated by Podwise.